|
I am a MS student in Electrical and Computer Engineering (ECE) at the University of California, San Diego (UCSD). Previously, I received my B.Eng. in Automation Engineering from Xi’an Jiaotong University (XJTU). I also spent a wonderful time as an exchange student at CUHK. My research interests lie in Video Understanding and Generative Modeling. Email / Scholar / GitHub / Hugging Face |

|
|
|
|
|
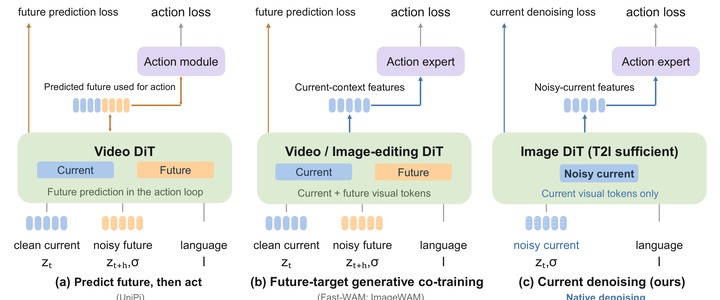
Zanyi Wang, Yuheng Lei, Dengyang Jiang, Ping Luo, Mengdi Wang, Zhixuan Liang, Shilong Liu Preprint, 2026 project page / arXiv / code Beyond forecasting: adapting generative visual structure to action learning through the native denoising trajectory. |

|
Zanyi Wang, Xin Lin, Haodong Li, Dengyang Jiang, Yijiang Li Preprint, 2026 code / arXiv Readout, not generation. |

|
Dengyang Jiang, Zanyi Wang*, Hengzhuang Li, Sizhe Dang, Teli Ma, Wei Wei, Guang Dai, Lei Zhang, Mengmeng Wang ACM International Conference on Multimedia (ACM MM), 2026 arXiv Transferring SAM to affordance grounding task and showing robust performance for both seen and unseen actions. |
|
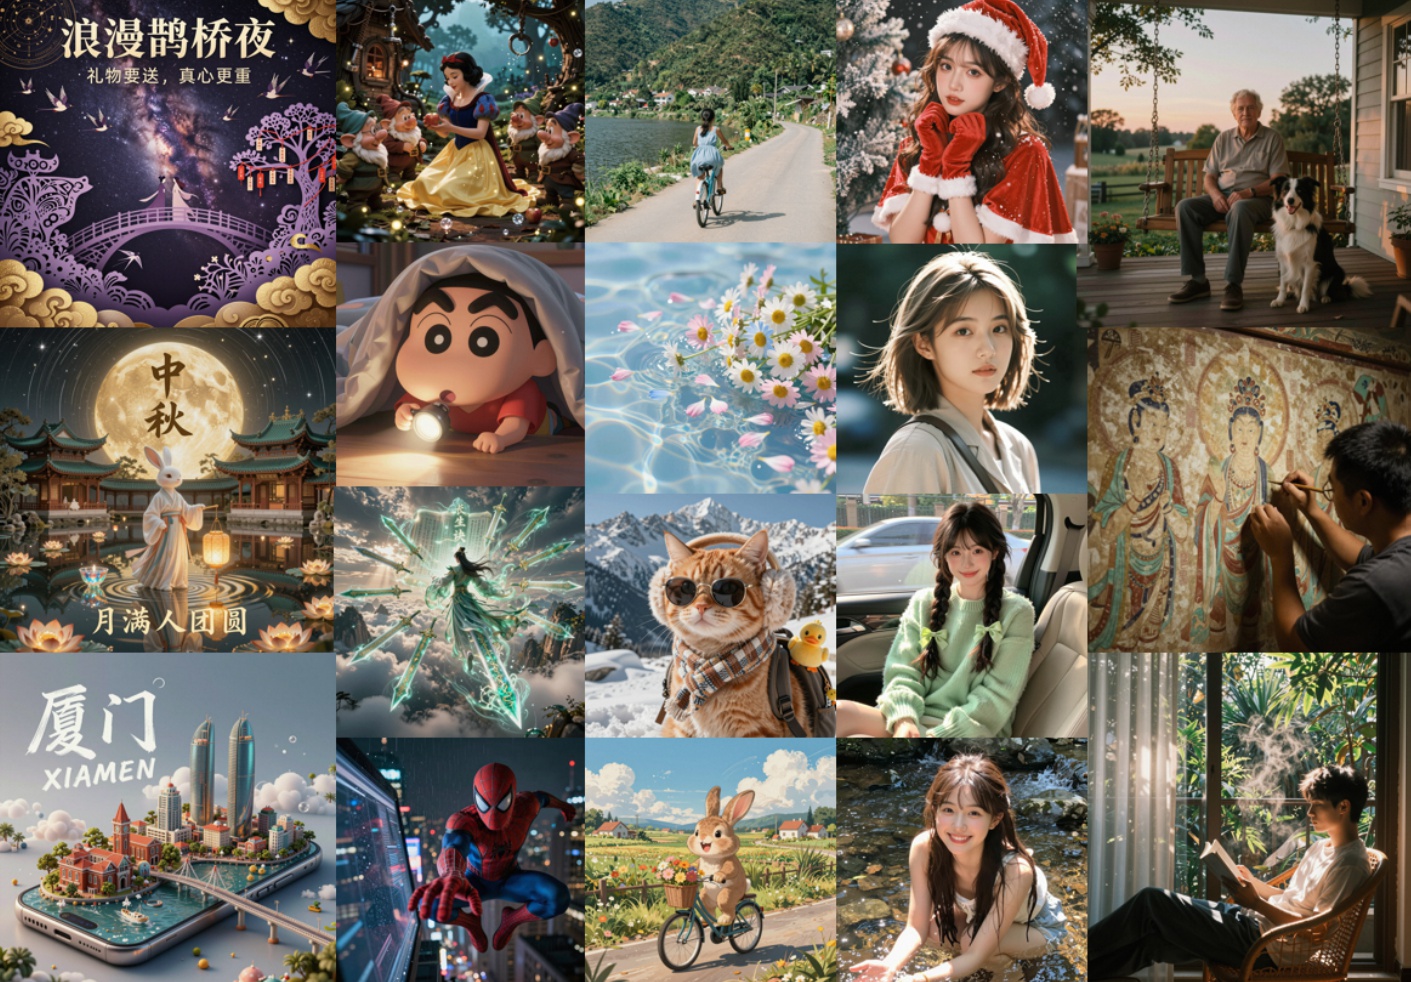
Dengyang Jiang, Dongyang Liu, Zanyi Wang, Qilong Wu, Liuzhuozheng Li, Hengzhuang Li, Xin Jin, David Liu, Zhen Li, Bo Zhang, Mengmeng Wang, Steven Hoi, Peng Gao, Harry Yang European Conference on Computer Vision (ECCV), 2026 code / arXiv Showing that DMD and RL can be trained simultaneously, with RL enabling the student model to surpass the teacher and DMD loss regularizing RL to prevent reward hacking. |

|
Zanyi Wang, Fan Li, Dengyang Jiang, Liuzhuozheng Li, Yunhua Zhong, Guang Dai, Mengmeng Wang Conference on Computer Vision and Pattern Recognition (CVPR) @ CV4Smalls WS, 2026 arXiv A parameter-efficient adaptation approach that successfully tackles complex spatio-temporal localization under strict small-data constraints. |
|
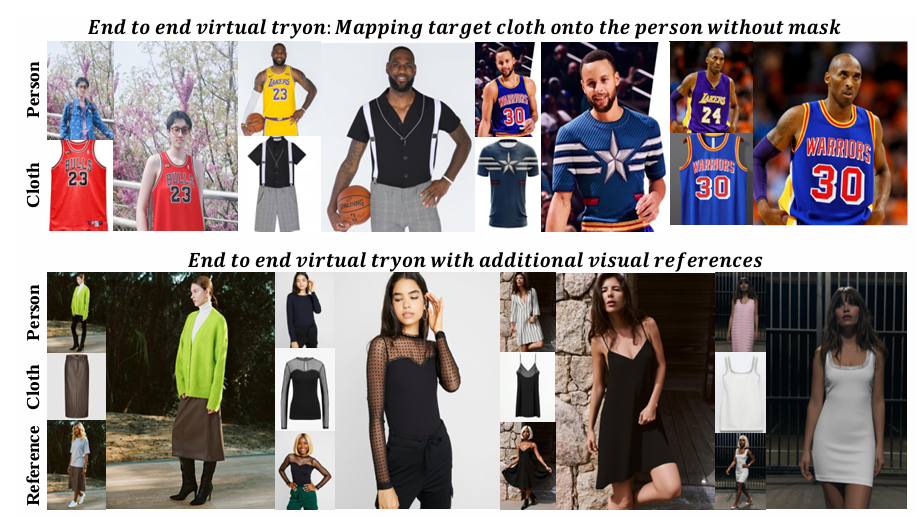
Liuzhuozheng Li, Yue Gong, Shanyuan Liu, Zanyi Wang, Dengyang Jiang, Liebucha Wu, Bo Cheng, Yuhang Ma, Dawei Leng, Yuhui Yin Conference on Computer Vision and Pattern Recognition (CVPR), 2026 code / arXiv An End-to-End Virtual Try-on model that directly fits the target garment onto the person image. |
|
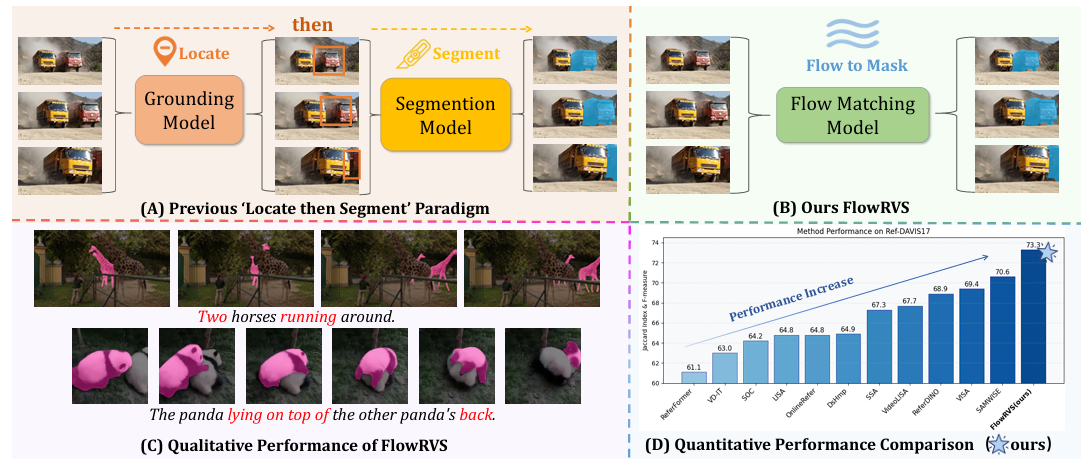
Zanyi Wang, Dengyang Jiang, Liuzhuozheng Li, Sizhe Dang, Chengzu Li, Harry Yang, Guang Dai, Mengmeng Wang, Jingdong Wang International Conference on Learning Representations (ICLR), 2026 code / arXiv / 机器之心 Reformulated RVOS as learning a continuous, text-conditioned flow that deforms a video's content into its target mask. |
|
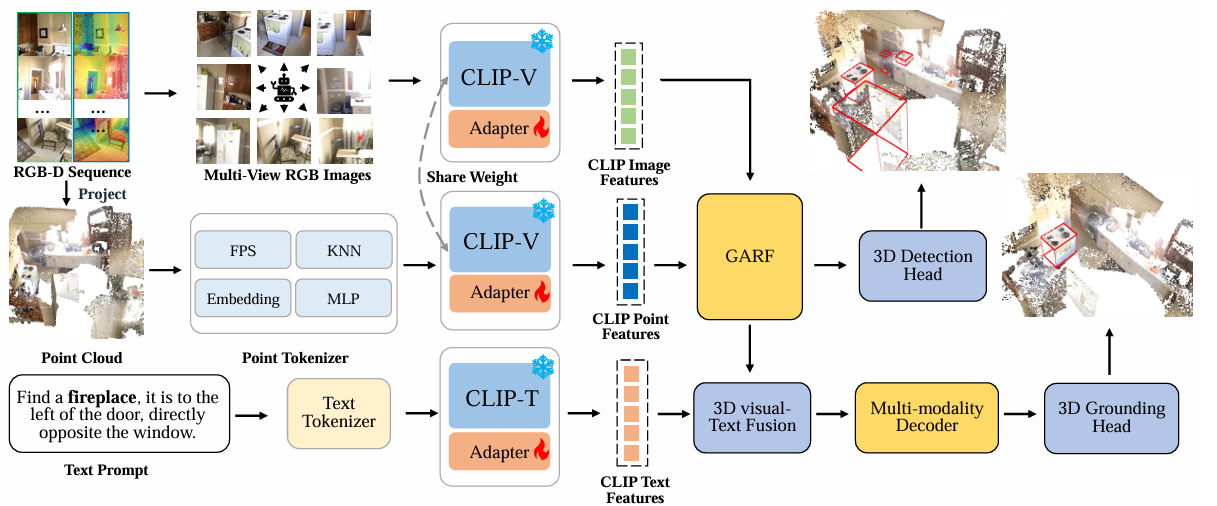
Fan Li, Zanyi Wang*, Zeyi Huang, Guang Dai, Jingdong Wang, Mengmeng Wang ACM International Conference on Multimedia (ACM MM), 2025 arXiv Developed a unified framework leveraging CLIP’s ViT encoder for efficient tri-modal 3D visual grounding. |

|
Dengyang Jiang, Xin Jin, Dongyang Liu, Zanyi Wang, Mingzhe Zheng, Ruoyi Du, Xiangpeng Yang, Qilong Wu, Zhen Li, Peng Gao, Harry Yang, Steven Hoi Advances in Neural Information Processing Systems (NeurIPS), 2026 project page / code / arXiv On-policy self-distillation for continuously tuning step-distilled diffusion models without sacrificing few-step capacity. |

|
Liuzhuozheng Li, Zhiyuan Zhan, Shuhong Liu, Dengyang Jiang, Zanyi Wang, Guang Dai, Jingdong Wang, Mengmeng Wang Preprint, 2026 code / arXiv Diffusion models can generate high-quality samples without timestep or class embeddings when noisy data manifolds are kept geometrically disjoint across timesteps. |
|
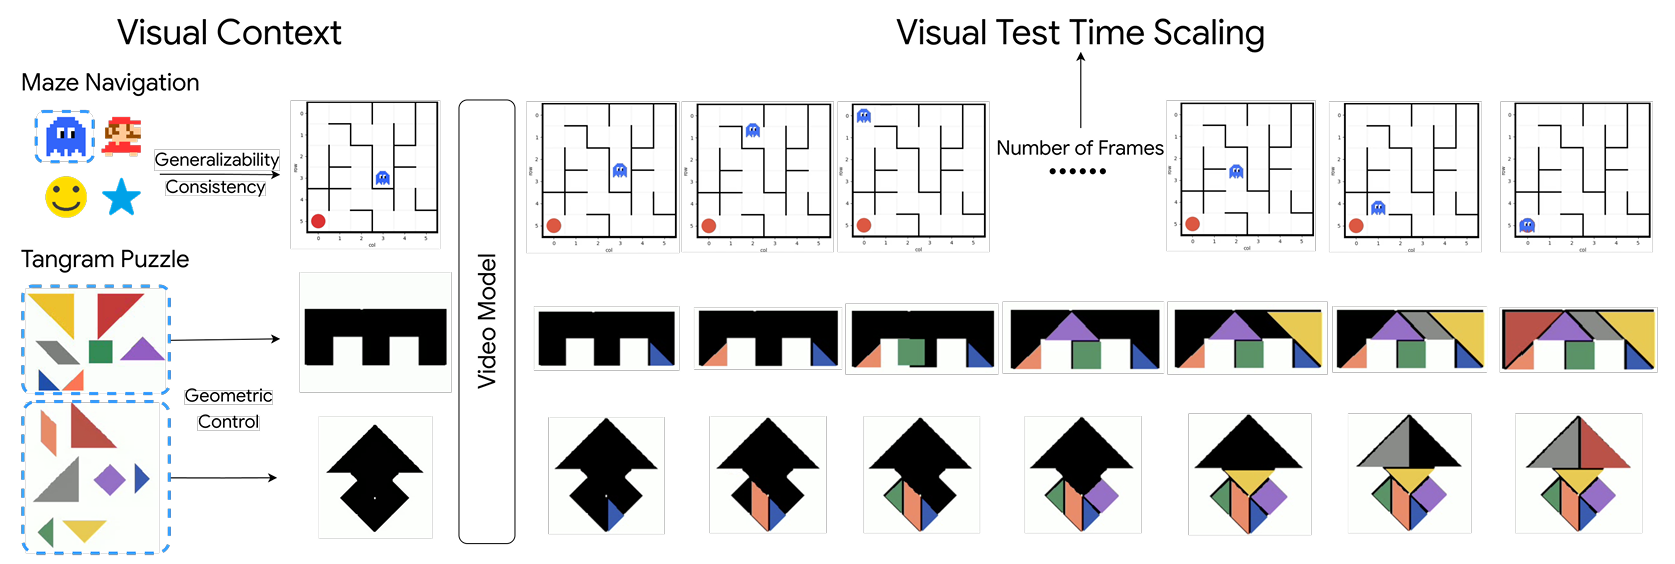
Chengzu Li, Zanyi Wang*, Jiaang Li, Yi Xu, Han Zhou, Huanyu Zhang, Ruichuan An, Dengyang Jiang, Zhaochong An, Ivan Vulić, Serge Belongie, Anna Korhonen Preprint, 2026 arXiv Exploring how visual context enhances video reasoning capabilities. |
|
Design and source code from Jon Barron's website. |